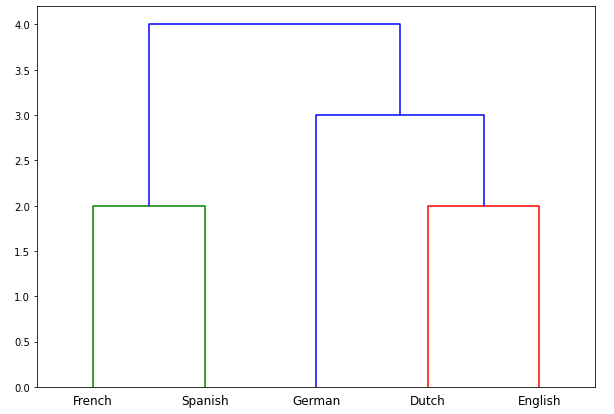
Thanks to Pat, Russell, and everyone contributing to this discussion. I particularly appreciate how the conversation moves from a simple demonstration of Levenshtein distance to questions about phonetic similarity, cognate comparison, and historical relationships between languages.
Aryaman’s question about comparing IPA strings using place of articulation, manner, and voicing is especially interesting. I think it points toward an important distinction: measuring differences between encoded symbols is not necessarily the same as measuring differences between speech sounds.
A few technical observations might help extend the discussion.
1. A small but important detail in the JavaScript implementation
In the example above, the substitution operation uses:
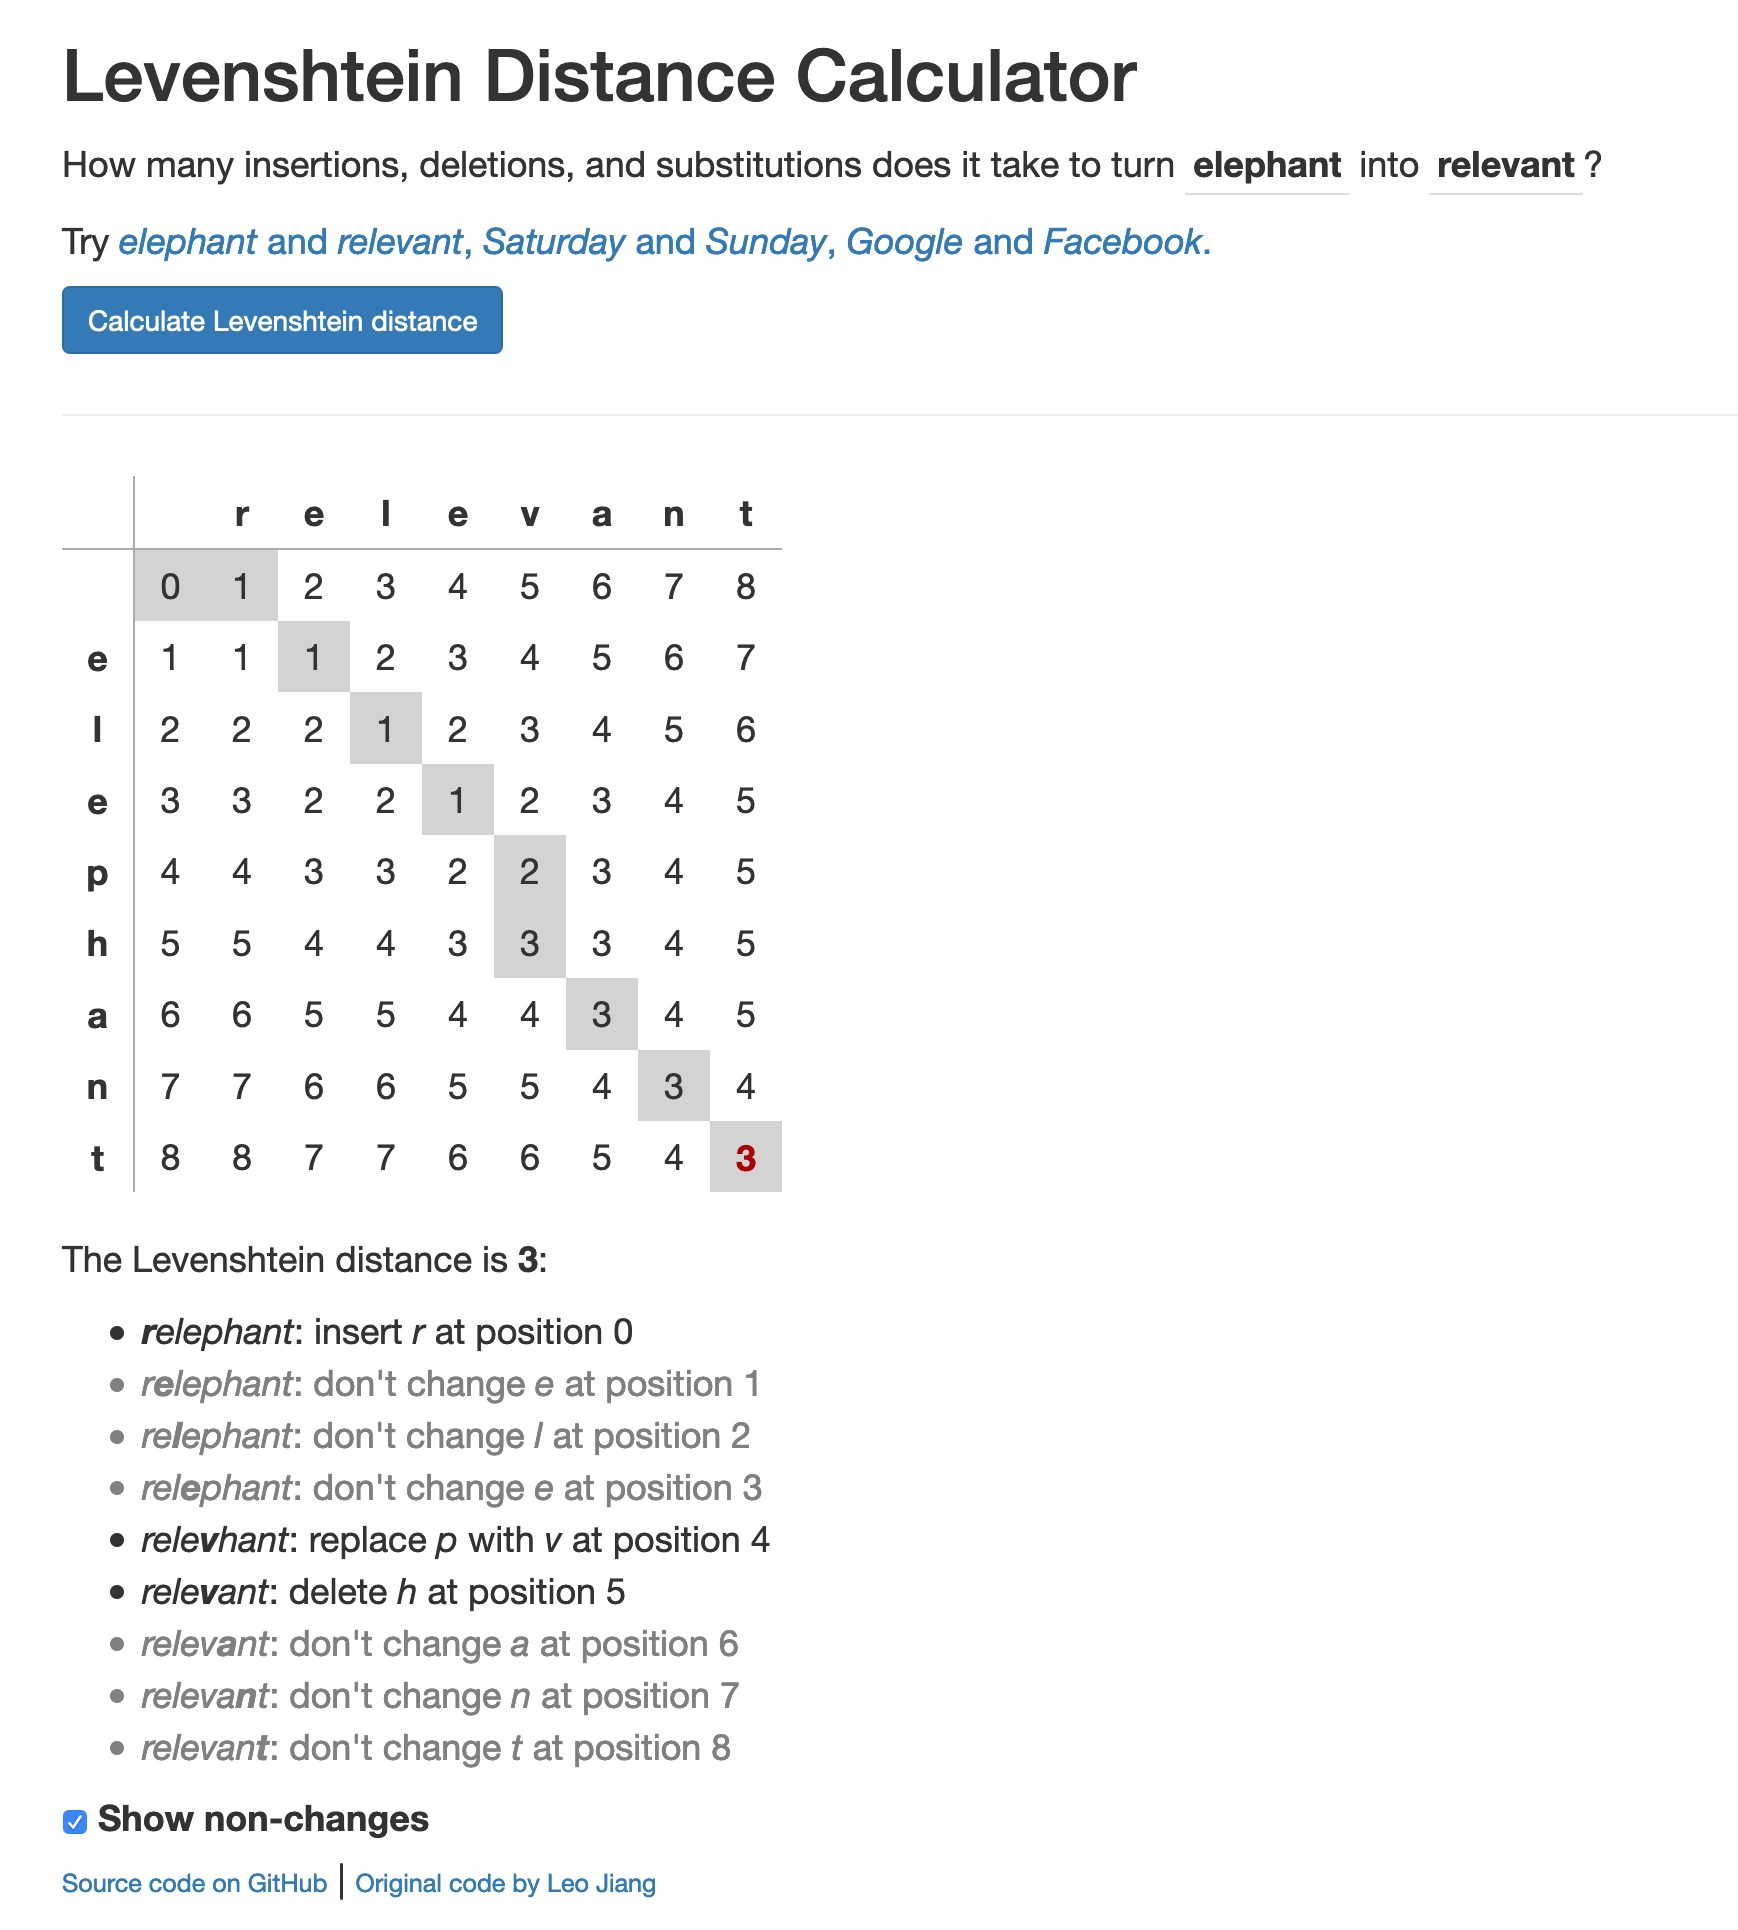
d[i-1][j-1] + 2
Classical unit-cost Levenshtein distance normally assigns a substitution cost of 1.
Using a substitution cost of 2, with insertion and deletion costs of 1, effectively produces an insertion/deletion-only edit distance, because substituting a symbol is never cheaper than deleting and reinserting it.
For example:
-
Standard Levenshtein: distance("p", "b") = 1
-
With substitution cost 2: distance("p", "b") = 2
Neither model is inherently useless, but the distinction matters when interpreting linguistic similarity.
This becomes particularly important if we introduce phonetic feature-based substitution costs.
2. Weighted Levenshtein distance over phonetic segments
Rather than treating every pair of different IPA symbols as equally distant, we could define a substitution cost based on phonetic features.
For instance:
-
/p/ and /b/ share place and manner of articulation but differ in voicing.
-
/p/ and /t/ share manner and voicing but differ in place of articulation.
-
/p/ and /s/ differ in both place and manner.
A weighted substitution function could therefore look conceptually like:
cost(x, y) = w_place × Δplace + w_manner × Δmanner + w_voice × Δvoice
The individual feature differences would need to be defined carefully, and the weights ideally estimated or validated against linguistic data rather than chosen arbitrarily.
The dynamic programming recurrence can remain essentially the same, but it would operate on sequences of phonetic segments with linguistically informed edit costs.
An important complication is that phonetic transcriptions do not always have a simple one-symbol-to-one-phone correspondence.
Affricates, combining diacritics, length markers, and suprasegmental features may require more careful segmentation and alignment.
3. Unicode normalization and phonetic segmentation
There is another subtle issue when comparing IPA transcriptions computationally.
Two strings can represent canonically equivalent text while using different Unicode code-point sequences. A naive comparison may count encoding differences that have no intended phonetic significance.
Canonical normalization, such as NFC, can help establish consistent representations.
However, normalization should not remove linguistically meaningful distinctions. IPA diacritics, for example, may encode important phonetic properties and should not simply be discarded.
Also, Unicode grapheme clusters and linguistic segments are not necessarily identical. Grapheme-aware segmentation can improve text handling, but phonetic alignment still requires its own segmentation policy.
This distinction between Unicode representation, normalization, segmentation, and edit-distance calculation is discussed in:
Unicode & Grapheme-Safe Levenshtein
4. Comparing cognates across multiple languages
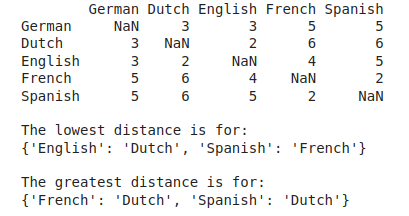
Russell’s proposal to calculate distances across multiple cognates and generate hierarchical clustering results is a promising direction for exploratory analysis.
I would suggest a few additional controls:
-
Compare words belonging to carefully aligned meaning or cognate sets.
-
Normalize distances with respect to sequence length, using a clearly documented method.
-
Separate missing data from genuinely dissimilar forms.
-
Avoid allowing languages with more available cognates to dominate aggregate comparisons.
-
Compare results obtained with unit-cost Levenshtein, weighted phonetic distance, and sound-class-based methods.
The LingPy sound-class models already mentioned in this thread provide a valuable starting point:
It would also be useful to examine whether the clustering remains stable when changing the substitution weights or the set of cognates included.
5. Surface similarity is not necessarily historical relatedness
I think the Greenhill (2011) paper mentioned above is particularly important here.
Two words can be phonetically similar because of shared ancestry, borrowing, chance resemblance, or other linguistic processes.
Likewise, related words can become substantially different through historical sound changes.
Consequently, Levenshtein distance is useful for measuring surface differences, but those distances alone cannot establish genealogical relationships between languages.
A broader discussion of where edit distance works well, and where its assumptions become limiting, can be found here:
Levenshtein Distance Limitations: When Edit Distance Fails
For reference, Greenhill’s original paper is available through the ACL Anthology:
Final thought
What I find most valuable about this discussion is that it illustrates how a mathematically simple algorithm can become much more informative when the sequence representation and edit costs are chosen with domain knowledge.
For linguistic applications, I would distinguish three separate questions:
-
How different are the encoded strings?
-
How different are the underlying phonetic sequences?
-
What do those differences tell us about historical linguistic relationships?
Levenshtein distance can help with the first two, especially when extended with phonetic features, but the third requires additional linguistic evidence.
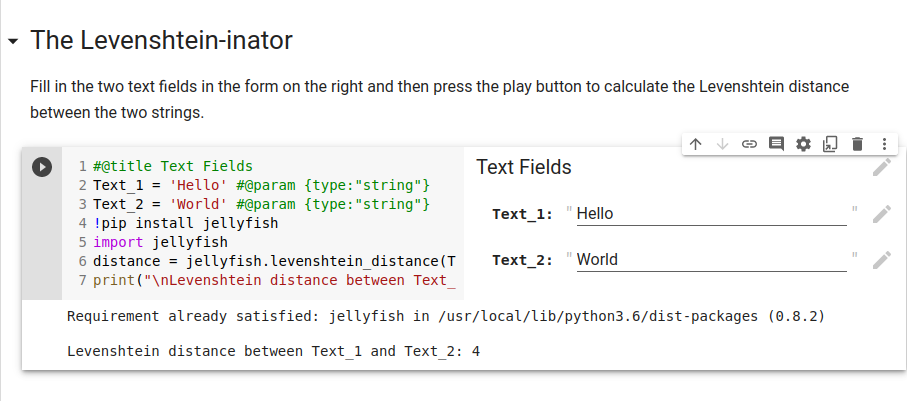
Thanks again for the thoughtful discussion and the shared Colab notebooks. I hope these observations are useful for anyone extending the experiments to larger multilingual cognate datasets.